The bottleneck in long-horizon agents isn't the model, it's the control loop
A new paper from Meta and collaborators shows that adding a lightweight controller that reasons over a compact run summary, rather than the full transcript, beats direct-control agents and even production coding agents like Codex and Claude Code on long-horizon benchmarks.
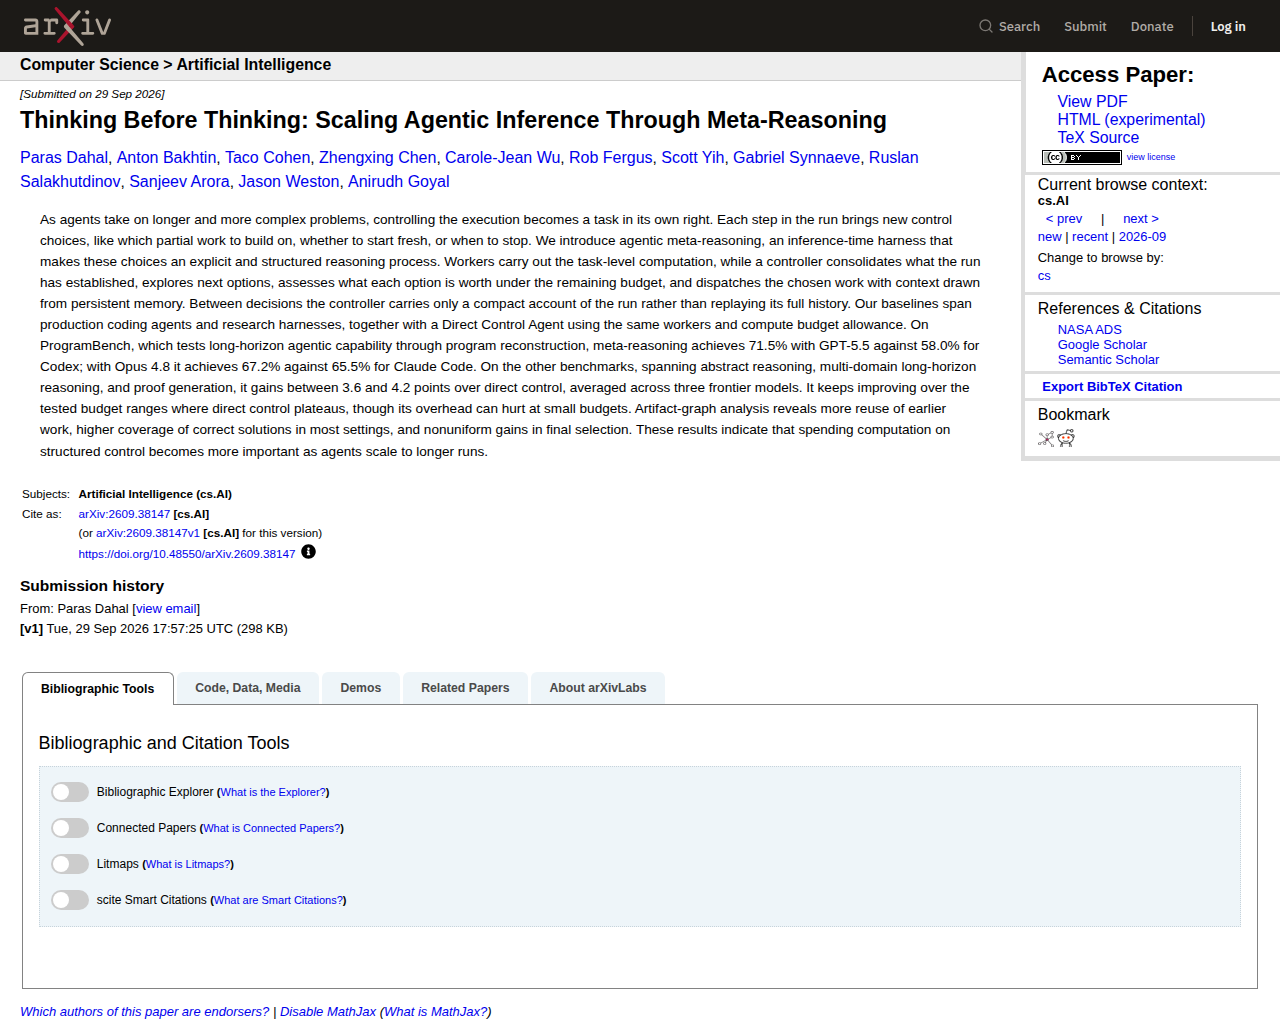
Every agent framework I've built or evaluated eventually runs into the same failure mode. The agent does good work early in a run, then the context window fills up with its own history, and by step forty it's re-deriving things it already figured out at step twelve, or worse, doubling down on an approach it should have abandoned. Most fixes treat this as a memory problem: bigger context, better retrieval, smarter summarization of the transcript. A paper out this week, Thinking Before Thinking: Scaling Agentic Inference Through Meta-Reasoning (Dahal, Bakhtin, Cohen, et al., including Jason Weston and Sanjeev Arora), argues that's the wrong frame. The problem isn't memory. It's that nothing in the loop is explicitly responsible for control.
The core move: split the run into workers and a controller
The architecture is a controller/worker split. Workers do the actual task-level computation — writing code, running tests, producing a proof step, whatever the domain calls for. The controller does none of that work directly. Instead, at each decision point it does four things: consolidates what the run has established so far, explores what options are available next, assesses what each option is worth given the budget remaining, and dispatches the chosen work to a worker with context pulled from persistent memory.
The detail that matters most: between decisions, the controller carries only a compact account of the run, not a replay of the full history. That's a deliberate constraint, not an omission. A direct-control agent's context grows monotonically — every tool call, every failed attempt, every dead end stays in the transcript, and the agent has to re-read all of it to decide what to do next. The controller in this paper instead maintains something closer to a working summary: what's been tried, what worked, what the current best artifact is, how much budget is left. That's the whole point of the title — the controller thinks before it acts, over a structured account of the run, rather than reasoning inline by rereading everything that's happened.

This is a familiar shape if you've worked with distributed systems — a scheduler that reasons over cluster state rather than every job's full log is not a new idea. What's notable here is applying that separation to agent inference, at the level of an LLM's own reasoning process, and measuring whether it actually pays for itself in compute.
The numbers, and why they surprised me
The baselines are what make this credible rather than just architecturally tidy. The authors compare against production coding agents — Codex and Claude Code — not just research harnesses, plus a Direct Control Agent that uses the identical workers and compute budget as the meta-reasoning setup, isolating the effect of the controller itself.
On ProgramBench, which tests long-horizon capability through program reconstruction, meta-reasoning with GPT-5.5 hits 71.5% against Codex's 58.0%. With Opus 4.8 backing both sides, it's 67.2% against Claude Code's 65.5% — a smaller gap, but notable because Claude Code has its own scaffolding tuned for exactly this kind of task, and it's still behind. Across the other benchmarks — abstract reasoning, multi-domain long-horizon reasoning, proof generation — meta-reasoning gains 3.6 to 4.2 points over direct control on average across three frontier models.
The result I'd flag hardest for anyone building agent products: meta-reasoning keeps improving as you give it more compute budget, in ranges where direct control plateaus. That's the actual argument for spending tokens on control logic rather than just more worker steps. But there's a real cost on the other side — the controller's overhead can hurt at small budgets, where you don't have enough runway to pay for the "thinking about thinking" and still get task work done. If you're running short, cheap agent tasks, this architecture is probably not worth the overhead. If you're running agents for hours against a real budget ceiling, it's a different calculation.
Why the artifact-graph findings matter more than the headline numbers
The paper's artifact-graph analysis is where I think the real signal is, more than the leaderboard numbers. It shows more reuse of earlier work under meta-reasoning, higher coverage of correct solutions in most settings, and — this is the part that reads as honest — nonuniform gains in final selection. That last point means the controller doesn't just find the right answer more often; sometimes it finds it just as often as direct control but is worse or better at picking it out of what's available. Control and generation are separable failure modes, and this paper is one of the few I've seen that measures them separately instead of collapsing everything into a single pass/fail score.
What this means if you're building agents
I don't read this as "add a controller layer to your agent," at least not casually. The lesson I'm taking is narrower: if your agent runs are long enough that the transcript itself becomes the bottleneck — not the model's capability, but its ability to reason over its own accumulating history — that's a control problem, and it deserves its own explicit reasoning step with its own budget, separate from the worker doing the task. For short-lived agent calls, this is overkill. For the long-horizon, multi-hour agent runs that more of us are shipping into production, treating control as a first-class thing to spend inference on, rather than an emergent property of a big enough context window, looks like the right direction. I'd rather add a small, well-scoped controller than keep throwing context length at a problem that's actually about what the agent chooses to remember.